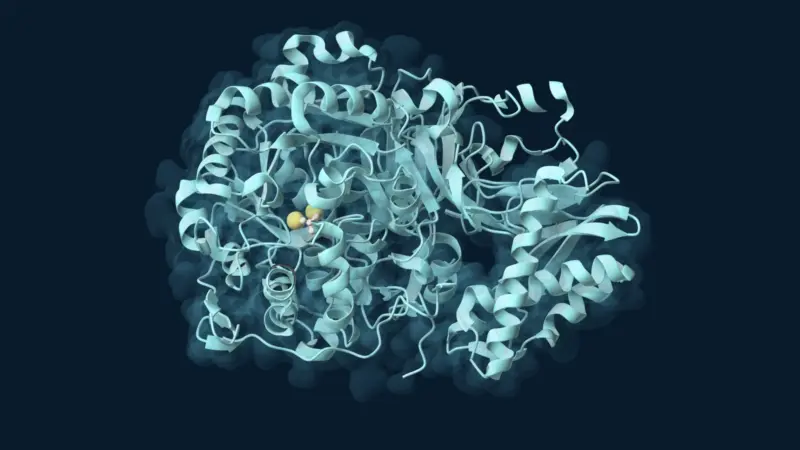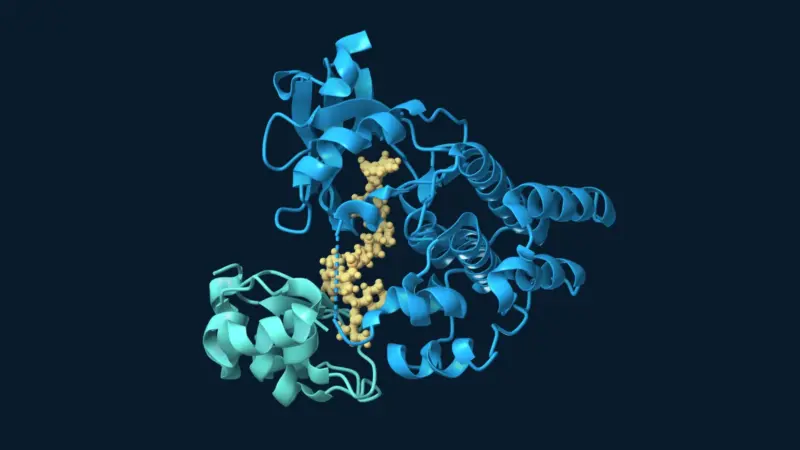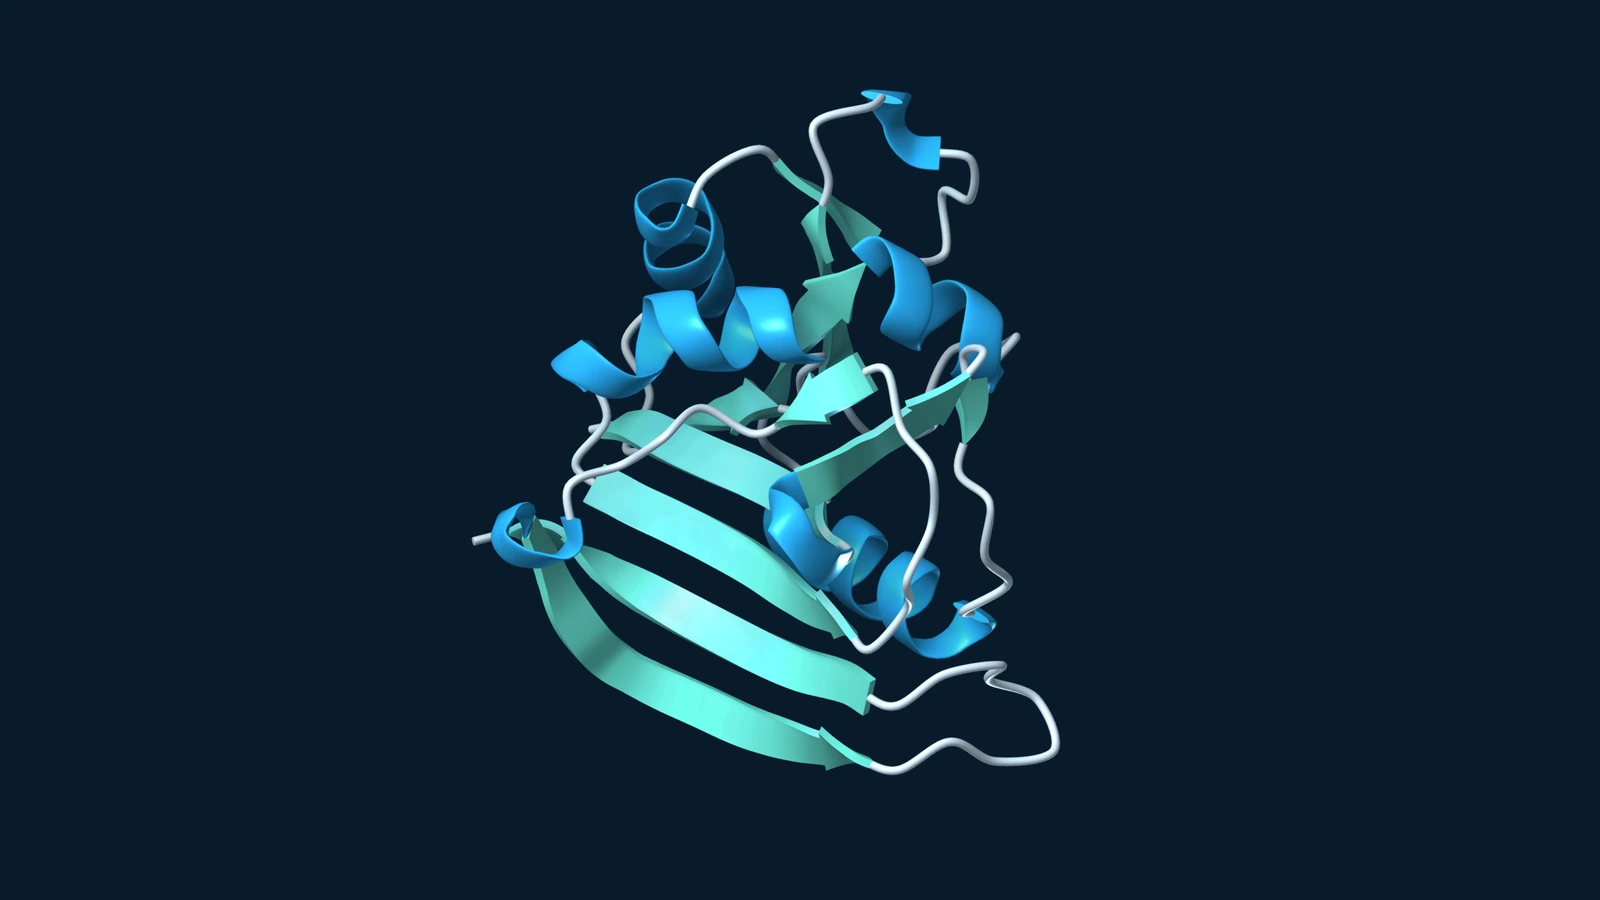
AlphaFold 2 made a difficult question easier to explore: what might an enzyme look like in three dimensions? Its predictions give researchers a starting point for investigating proteins whose structures have not been determined experimentally. The useful detail comes with an essential companion: information about where the model is uncertain.
Developed by DeepMind and described by John Jumper and colleagues in Nature in 2021, the system achieved a major improvement in the CASP14 structure-prediction assessment. That achievement concerns predicting protein structure. It does not mean that every predicted atom is correct or that a model establishes an enzyme’s biological activity.
How AlphaFold 2 builds a structural prediction
The method combines a protein’s amino acid sequence with information from related sequences and, where available, structural templates. Its trained neural network uses these inputs to estimate the protein’s three-dimensional arrangement.
During a prediction, the network can pass its output through further rounds of refinement, a process called recycling. These rounds revise the structural prediction while using already trained model parameters. Ordinary use does not retrain the system every time someone submits a sequence.
Changes in input databases, model versions or settings can nevertheless change the result. Keeping a record of those choices matters when another researcher needs to reproduce a prediction.
Confidence belongs beside the picture
A protein model can look convincing even where the calculation is uncertain. AlphaFold’s confidence measures help users judge which parts deserve closer attention.
The pLDDT score estimates confidence in local structure. Predicted aligned error, or PAE, helps assess the relative placement of regions. A pair of individually well-predicted domains can still have an uncertain orientation relative to each other.
Low-confidence regions can include flexible or disordered segments that do not adopt one stable shape in isolation. They should not automatically be treated as a well-defined surface for docking a drug or choosing an engineering mutation. Confidence is also an estimate, so a high score does not replace experimental testing.
What this offers enzyme researchers
A structural model can suggest where catalytic residues lie, help compare related proteins and guide the choice of experiments. It can also reveal a plausible fold when sequence information alone leaves the protein difficult to interpret.
However, enzyme function depends on more than one static arrangement. Substrates, metal ions, cofactors, interacting proteins and movement during a reaction can all matter. Standard AlphaFold 2 does not explicitly place small-molecule substrates or cofactors, and a predicted pocket does not demonstrate a drug’s binding strength or clinical benefit.
Likewise, predicting two similar structures for an enzyme and its mutant does not prove that the mutation has no functional effect. Activity and stability measurements remain necessary when evaluating a redesigned protein.
Faster access still has practical limits
Looking up an existing model in the AlphaFold Protein Structure Database can be quick. Running a new prediction is a different task: its duration depends on sequence length, hardware, database searches and the chosen pipeline.
The official software’s timing benchmarks explicitly exclude sequence-alignment and template-search time. They should not be read as a promise that every enzyme can be modelled from scratch in a few minutes.
AlphaFold 2’s contribution is a much more accessible structural starting point for research. For the later extension to broader molecular interactions, see our separate, dated report on AlphaFold 3.
Sources
- Jumper, J., Evans, R., Pritzel, A., et al. (2021). Highly accurate protein structure prediction with AlphaFold. Nature, 596, 583–589. DOI: 10.1038/s41586-021-03819-2.
- Google DeepMind: official AlphaFold 2 inference documentation.
- EMBL-EBI: confidence scores, strengths and limitations and the AlphaFold Protein Structure Database.
Update note: This revision corrects the earlier claim that routine predictions continually retrain AlphaFold 2, qualifies accuracy and runtime claims, and explains the limits of using structural models to infer enzyme function or drug binding. The original publication date and URL are retained.